Open-source clinical AI · DIGI at the University of Washington
Practical, verifiable AI for clinical care.
Open-source tools for patient-chart questions and health-system reporting—built so clinicians and analysts can inspect every source record, query, and check behind an answer. Backed by a shared clinical context engine, a 4-layer evaluation harness, and post-training research for compact open-weight models.
Clinician-facing chart Q&A and reviewed population reporting
Each client application integrates directly into an established open-source health system workflow, keeping source records, SQL queries, and provenance inspectable before any clinical or operational decision is made.
Point-of-Care EHR · OpenMRS O3
ChartSearchAI
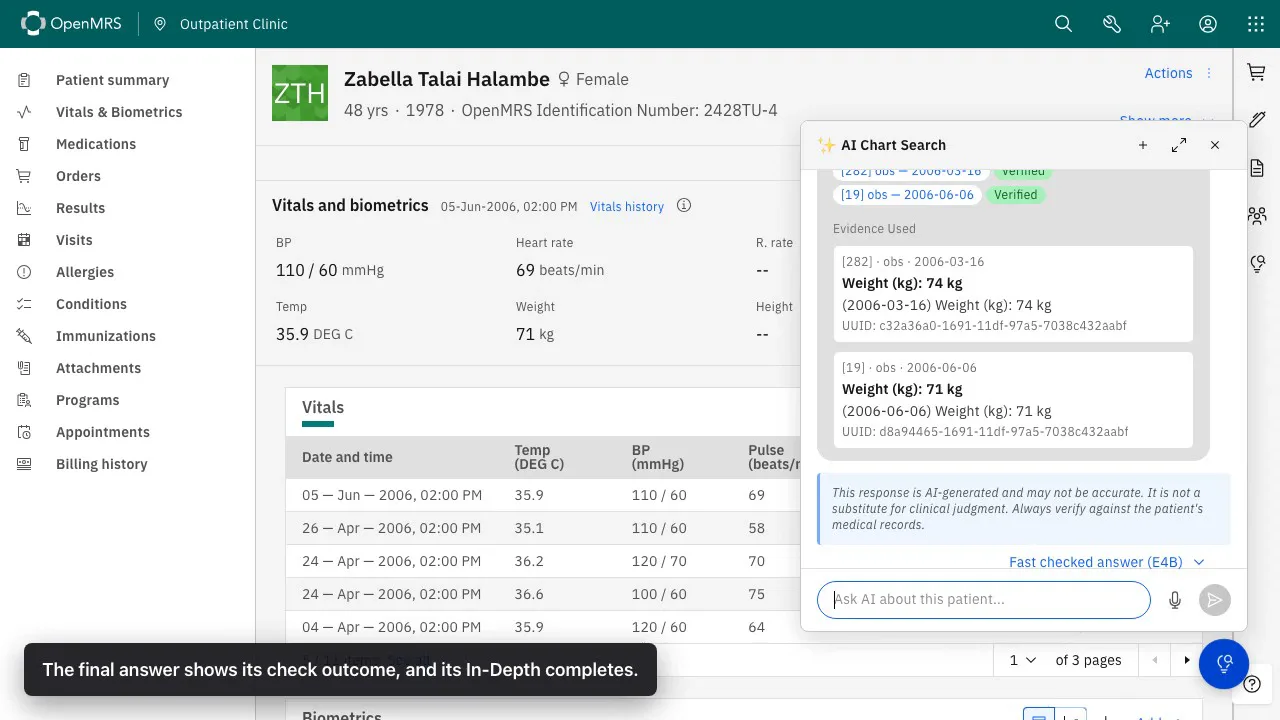
Ask natural-language questions inside an OpenMRS patient chart and inspect every cited clinical record.
Streams answers directly inside the patient chart using either OpenMRS's bundled single-model path or the shared Med Agent Hub pipeline with QueryStore context caching, deterministic temporal rules (R1–R10), and inline UUID provenance badges.
Draft, review, inspect, and execute schema-grounded SQL queries and publish verified cohorts to Apache Superset.
Translates laboratory and HIV program questions into auditable SQL across a 4-stage human-in-the-loop lifecycle (Draft → Review → Inspect → Execute), supporting direct database schemas as well as CSV and FHIR reporting pipelines.
Looking for regional pilots and applied health-information exchange projects?
Explore our Projects catalog—including the patient-mediated longitudinal FHIR R4 / IPS summary initiative—where OpenClinAI components are applied to multi-clinic health system challenges.
Med Agent Hub: shared clinical context, deterministic rules, and checked answers
Small and mid-sized open-weight models fail when handed raw, noisy EHR exports or unverified single-shot prompts. Med Agent Hub sits behind client applications to normalize clinical context, surface guideline rules before generation, and verify every claim against source records.
Layer A · Context Ingestion
QueryStore & 5-Tier Lossless Condenser
Caches normalized OpenMRS patient snapshots in QueryStore and condenses multi-clinic FHIR R4 bundles across 9 token budgets (256k down to 1k) with an explicit [Completeness Manifest] and conditional Tier-0 raw note/lab overflow recovery.
Layer B · Pre-Generation Intelligence
Clinical Entity Graph & 4-Layer KB
Deterministically links medications, conditions, renal/lab safety thresholds, and note-vs-structured contradictions (ClinicalEntityGraph) while injecting scoped clinical reference rules from WHO SMART Guidelines, KDIGO, ADA, CDC ACIP, RxNorm, and LOINC.
Exposes stream-isolated model profiles (openmrs-*, catalyst-sql-*, wahs-*, lab-laya-*) backed by local Apple Silicon / Linux engines (llama-router, MLX, vLLM) or authenticated Cloud GPU relays across Gemma 4, MedGemma, and Qwen3.
Validation Harness & The 4-Layer Clinical Verification Stack
Generic LLM-as-a-judge averages hide rare, high-severity clinical omissions and fabricated citations. The Validation Harness evaluates clinical AI systems across a 4-layer verification hierarchy, interactive streaming telemetry, and 34 published evaluation reports.
Layer 1 · Deterministic Oracles
Provenance, Temporal, SQL & CQL
Zero-variance programmatic checks run on every output: exact FHIR/OpenMRS UUID citation binding, temporal window gates, PostgreSQL row-set equivalence (_compare_row_sets), and deterministic WHO SMART L3 CQL execution (cqf-ruler).
Layer 2 · System-1 Encoders
Pinned Local Entailment Verifiers
Fast, reproducible single-pass cross-encoders (Laya ~0.4B) verify claim-to-record entailment (supported / partly / unsupported) and appropriate abstention in under 50 ms without generative API drift.
Layer 3 · Multi-Family Autoraters
17-Dimension Rubric & Safety Floor
Blinded cross-family LLM judge panels (Claude Opus, GPT-5.4, Gemini 3.1 Pro) score a 3-Domain × 17-Dimension clinical taxonomy that separates Comprehensiveness from Critical Safety Omissions (Safety-Adjusted Benchmark) and measures perturbation F1_floor.
Layer 4 · Clinician Calibration
Blind Adjudication & PPI Intervals
Practising clinicians perform dual blind review on stratified subsets, paired with Prediction-Powered Inference (ppi_benchmark) to rectify LLM autorater bias, compute valid 95% confidence intervals, and score Script Concordance (SCT) under uncertainty.
Non-autoregressive clinical verifiers and the 5-rung post-training ladder
Our AI engineering lab investigates how far sub-billion System-1 encoders and compact 1.7B–4B open-weight generators can be pushed on edge and single-GPU clinic hardware when trained against deterministic clinical and execution oracles.
Calling a second generative LLM pass just to check citations or filter chart records consumes 25% of turn latency (1.5–4.0s). We evaluate compact single-forward-pass encoders (Laya ~0.4B vs. Jev-1.13 reference) across two clinical gating tasks:
Phase 0a — Context-Admission Relevance: 5-fold Leave-One-Patient-Out (LOPO) evaluation across 7,840 clinical record–topic pairs under a recall-first safety gate (≥99% must-include record recall).
Logit Temperature Calibration: Post-hoc temperature scaling (T = 3.297) reduces Expected Calibration Error (ECE) from 0.466 to 0.081 without changing ranking AUROC.
Track B · Generative Post-Training
The 5-Rung Post-Training Ladder for Edge Clinical Models
A controlled experimental progression testing where inference-time compute stops and weight adaptation begins for 1.7B–4B clinical models (Gemma 4 E2B/E4B, Qwen3 1.7B/4B):
Built for real clinical workflows and transparent evidence
OpenClinAI is developed by the Digital Initiatives Group at I-TECH (DIGI) at the University of Washington. We focus on open-source health systems used across global health and public-sector care delivery, including OpenMRS, OpenELIS Global, Apache Superset, and FHIR R4 exchanges.
Demonstration sites, recordings, and benchmark reports use synthetic or de-identified evaluation data. They are research and engineering evidence, not clinical guidance or certification of clinical safety.
Evidence & Project Links
Browse dated evaluation reports, architecture comparisons, and upstream open-source contributions.